Safe Home Networks

Building and maintating a safe home network today has become both more difficult and more necessary than ever now that IoT, the Internet of Things, has filled our homes with smart devices that are hackable computers. I’ve talked about the necessity of securing IoT on home networks here and here, but now I’ll get down actions that increase control of your network of screenless computing devices.

I was tempted to begin this post with a shot at shaming folks into home network security: “you can’t manage what you can’t measure.” The quote has been attributed at various times to Edward Deming and Peter Drucker, two thinkers who have shaped my notions of management of computer systems.

But, you know, that saying is hogwash and neither Deming nor Drucker said it.

There’s no question that both Drucker and Deming favored measurement and data, but they never fooled themselves into avoiding management when metrics were lacking. You can manage a home network with a reasonable effort to gather data without the tedium that drives you to neglect security. Always shoot for tangible benefits, not perfection.

Network elements and safe home networks

Telecommunications IT uses a technical term: network element, which I like. The term is general enough to capture everything important about your home network. My rough and ready definition of a network element is “anything that matters on a network.”

The apps you have installed on your phones, laptops, and tablets, the services you subscribe to, along with the devices themselves, are network elements. The smart sensors and apps that control your thermostat, your kitchen appliances, and your security system are also network elements. Anything that affects the safety, efficiency, or usefulness of your network is a network element.

Well-managed IT environments maintain something called a configuration management database (CMDB), which is an inventory of network elements. Thousands of entries are common in the CMDB of a medium size business.

CMDBs are, frankly, a pain to maintain. Enterprises invest heavily in automating CMDB creation and maintenance. An accurate CMDB tells technicians where to look to solve problems. More important, they are also a roadmap for heading off issues before they occur.

Whether you solve your own home network issues or call in an expert, the equivalent of a CMDB will help maintain a safe home network.

Home CMDBs

A few years ago, the idea of a home CMDB was preposterous overkill. Typical home networks consisted of some kind of modem for connecting to the Internet, a personal computer, and maybe a printer. That’s all of three network elements. Not even worth entering in a spreadsheet. In the early days of home computing, looking over your desk and glancing at the floppy disks and CDs in the old shoebox next to your PC did as much as you could wish for a CMDB.

That was the old days. As I am writing this, I have 16 devices connected to my home router and an additional 16 that have connected recently, for a total of 32 devices. Worse, when I look at the device list on my router, a few of the entries are familiar, but most of them show as strings of hexadecimal digits (0-9 and A-F).

Unless your brain is staggeringly computation oriented, a list like that is meaningless. After fifty years of working with computers, I’m used to reading hexadecimal, but the device list on our home router is still tough.

Nevertheless, that wild list contains all the hardware network elements for effective CMDB and safe home network.

Let’s tame it.

IP and MAC addresses

On current networks, all devices have two addresses, some also have a name. One address is called the IP address. IP stands for “Internet Protocol”. This address shows where the device is connected to the network. If you know the IP address of a device, you can send a message to it. Great. But an IP address is only temporary, changing as devices move around and network conditions change. The IP address of your laptop is one thing when you’re at home, and a different address when you’re at a coffeeshop, school, work, or wherever, as your connection to the network changes.

Every device that connects to the network has a second address called the Medium Access Control address, or MAC. MACs are unique serial numbers that are burned in when a network connection component is manufactured. They appear as a sequence of 12 hexadecimal digits, usually separated into groups of 2 with a hyphen (-) or a colon (:). They are fixed until replaced or physically altered. The MAC can be used to trace the manufacturer of the component.

Well, that used to be true. There are now ways to change MAC addresses in software. But for now, assume MAC addresses never change because it is unlikely in a home network.

The network name of a computer is usually assigned by the user when the operating system, like Windows, is installed. Depending on the imagination of the owner, network names can be mundane like “MyPC” or fanciful, like “SherlocksDamnEggPlant”. These names are seldom seen outside local networks and often go a long way toward making CMDBs comprehensible. Unfortunately, many devices don’t have a network name, or they are hexadecimal gobbledygook, usually the device’s MAC.

Network names are human friendly, IP addresses direct messages, and MAC addresses unambiguously identify devices. In real life, Jim Smith is the equivalent of a network name, his street address is like an IP address, and his social security number is his MAC address. “Jim Smith” is not enough to pick your Jim from the thousands of Jim Smiths out there. With his street address you could send him a letter, but to really nail old Jim, you need his social. It’s the same on a network. But most of the time, for practical home network management, you need a recognizable network name to go with the MAC.

Tracking network elements at home

If your connected device list is all recognizable network names, you’re home free, but that’s not likely. So the first task in taming that connected device list is to figure out some way to make the list from your router understandable.

Finding the MAC of a Windows, Apple, Unix, or Linux computer is easy. On a Windows PC, you can go to the command or the PowerShell window and enter “ipconfig /all”. You’ll get a screenful of information. Look for the “Physical Address”, Microsoft’s term for MAC. On Linux or Unix, on a command line, type “ifconfig -a”. Again, you’ll get a screenful. Find the line that begins “ether”, “HWaddr” or “lladdr”. Look for 12 hexadecimal digits separated by hyphens or colons.

You can find MAC addresses for your phones in the system settings. You may have to poke around. Look for MAC address, physical address, Wi-Fi address, and other variations. It will always be 12 hex digits.

For other devices, finding the MAC is a pain but possible. Frequently, you can go to the settings for the device and find the MAC under network settings. However, it’s not always easy. For example, I could not find a MAC address for the Amazon Firesticks we have on our TVs.

The procedure I followed was to go around the house making a list of all the MACs I could find with descriptions of the devices. That still left me with several unexplained entries on the router list. A network with unknown devices is not a safe home network.

Network scanning apps

My next step was to look for network scanning apps. Several are available for Android, and I assume for iPhones. I tried some. As near as I can see, they all scan local network traffic for MACs, then use the MAC to guess the device. The guesses are not perfect. Fing, the best of the Android scanning apps I tried, told me that my Microsoft Surface Pro tablet was a Lumia smart phone: the correct vendor, but the wrong device. However, Fing did identify the two Amazon Firesticks we have in use and offered clues to other devices on my router’s list.

Dead reckoning

I happened to install a new simple monochrome laser jet printer on our network this week, which illustrated what I consider the proper way to maintain a home CMDB. After connecting the printer to the wireless network, I checked the router device list and noted the MAC of the new entry. Done. Accurate and easy. Do that every time you add a new device and your home CMDB is always right.

Another dead reckoning type solution is to change the password on your home network and force every device to re-register and record the devices as you give them the new password. That’s a sensible step to take occasionally anyway, especially if, like me, you are willing reveal your network password to guests when they want to use your network connection. However, the more people and devices that have your password, the greater the chances of intrusion.

Your guest may not be malicious, but if their device on which your network password has been entered inadvertently falls into bad hands, an intruder may be able to extract the password to your network. If there are teenagers in your house, they are likely to be casual about passing around wireless access, which doesn’t bother me, but they and their guests are also more careless than experienced and wary adults about losing devices.

My approach is to change the network password after I offer access to all but the most trustworthy of guests. In 2020, a year in which we have had few guests, I haven’t changed our password at all.

Record keeping

What do you do with this compiled information? For a list of 30 devices, a spreadsheet like Microsoft Excel would work well. But I have a simpler solution. On my home network, I have a Technicolor router-cable modem supplied by Comcast, which is not my favorite corporation, but the fastest and most reliable source for home broadband in my area. I’ve used various modems, routers, Wi-Fi endpoints and other networking gear in the past, and lately have settled on the convenience of a router-modem supplied by my service vendor.

The router management app supplied by Comcast is much better than some I have used. It supports user comments on the device listing, which is a useful feature. Instead of an independent spreadsheet, I’ve added comments explaining each entry exactly. So far, this has been both easy and effective.

In a future posting, I will get more into how you can use this rough and ready CMDB to help solve issues on your home network as they arise.
Supply Chain Management: Averting a Covid-19 Catastrophe

Yossi Sheffi is a supply chain management expert who moves freely between business and academics. He founded several companies, and he sits on the boards of large corporations. He teaches engineering at MIT and has authored a half-dozen books that are read by engineers, economists, and business people. When I heard about his latest book, The New (Ab)Normal, in which he tackles the covid-19 disruption of the global supply chain, I got a copy as soon as I could, stayed up late reading, and got up early to finish it.

gosling-supply-chain
The gosling supply chain management system

The New (Ab)Normal

New (Ab)Normal was worth it. Sheffi’s insider views are compelling. He has talked with the executives and engineers who struggled to put food and toilet paper on supermarket shelves, produce and distribute medical protective gear, and prevent manufacturing plants from foundering from supply disruption.

Supply chains and the media

Sheffi has harsh words for some media. For example, he says empty supermarket shelves were misunderstood. Food and supplies were never lacking, but they were often in the wrong place. Until the lockdowns in March, a big share of U.S. meals were dispensed in restaurants, schools, and company cafeterias. These businesses purchase the same food as families, but they get it through a different supply network and packaged in different ways.

Cafeterias buy tons of shelled fresh eggs in gallon containers, but consumers buy cartons of eggs in supermarkets for cooking at home. When the eateries shut down or curtailed operations and people began eating at home, plenty of eggs were available, but someone had to redirect them to consumers in a form that was practical for a home kitchen. Sheffi says food shortages appeared in dramatic media video footage and sound bites, but not in supply chains.

Bursty services

Changing buying patterns worsened the appearance of shortages. Supermarket supply chains are adjusted to dispense supplies at a certain rate and level of burstiness. These are terms I know from network and IT service management. A bursty service has bursts of increased of activity followed by relatively quiet periods. At a bursty IT trouble ticket desk, thirty percent of a week’s tickets might be entered in one hour on Monday morning when employees return to work ready to tackle problems that they had put off solving during the previous week. A less bursty business culture might generate the same number of tickets per week, but with a more uniform rate of tickets per hour.

Bursty desks must be managed differently than steady desks. The manager of a bursty service desk must devise a way to deploy extra equipment and hire more staff to deal with peak activity on those hectic Monday mornings. Experienced managers also know that an unpredicted burst in tickets on a desk, say in the aftermath of a hurricane, will cause havoc and shortened tempers as irate customers wait for temporarily scarce resources. The best of them have contingency plans to deal with unanticipated bursts.

Cloud computing to the rescue

The rise of cloud computing architectures in the last decade has yielded increased flexibility for responding to bursts in digital activity. Pre-cloud, managers who had to provide service through activity bursts had to deploy purchased or leased servers with the capacity to handle peak periods of activity. Adding a physical server is a substantial financial investment that requires planning, sometimes changes in the physical plant, often added training and occasionally hiring new personnel.

Worse, the new capacity may remain idle during long non-peak periods, which is hard to explain to cost conscious business leaders. Some businesses are able to harvest off-peak capacity for other purposes, but many are not. Cloud computing offers on-demand computing with little upfront investment, greatly reducing the need to pay for unused capacity to improve service during peak periods.

The food supply

Covid-19 caused an unanticipated increase in the burstiness of supermarket sales. Under the threat of the virus, consumers began to shop once a week or less, buying larger quantities. Folks accustomed to picking up a few vegetables and a fresh protein on their way home from work began arriving at the store early in the morning to buy twenty-five-pound sacks of flour and dry beans, cases of canned vegetables, and bulk produce.

On the supply end with the farmers and packers, the quantities sold per month stayed fairly constant because the number of mouths being fed did not change, but in the stores, by afternoon, shelves were bare waiting for shipments arriving in the night because consumers were buying in bursts instead of their “a few items a day” pattern. This made for exciting media coverage of customers squabbling over the products remaining on the shelves. The media seldom pointed out that the shelves were full each morning after the night’s shipments had arrived and were on the shelves.

Toilet paper

The infamous toilet paper shortage was also either illusory or much more nuanced than media portrayals. Like restaurants and cafeterias, public restrooms took a big hit with the lockdowns. Like food, toilet paper consumption is inherently constant, but toilet paper purchasing burstiness and where the product is purchased varies.

Commercial toilet paper consumption plummeted as shoppers began to purchase consumer toilet paper in the same bursts that they were purchasing food supplies. There may have been some hoarding behavior, but many shoppers simply wanted to shrink their dangerous trips to the market by buying in bulk. Consumer toilet paper is not like the commercial toilet paper used in public restrooms, which is coarser and often dispensed in larger rolls from specialized holders. This presented supply problems similar to food supply issues.

Supply disruption

Supply chains had to respond quickly. Unlike digital services, responding to increased burstiness in supermarket sales required changes in physical inventory patterns. Increasing the supply of eggs by the dozen at supermarkets and decreasing eggs by the gallon on kitchen loading docks could not be addressed by dialing up a new batch of virtual cloud computers. New buying patterns had to be analyzed, revised orders had to be placed with packers, and trucks had to roll on highways.

Advances in supply chain management

Fortunately, supply chain reporting and analysis has jumped ahead in the last decade. Consumers see some of these advances on online sales sites like Amazon when they click on “Track package.” Unlike not too long ago when all they were offered was Amazon’s best estimated delivery date, they see the progress of their shipment from warehouse through shipping transfer points to the final delivery. Guesswork is eliminated: arrival and departure is recorded as the package passes barcode scanners.

The movement data is centralized in cloud data centers and dispensed to the consumer on demand. Many people have noted that Amazon shipments are not as reliable as they were pre-covid. However, the impression of unreliability would be much stronger without those “Track package” buttons.

Supply chain managers have access to the same kind of data on their shipments. In untroubled times, a shipping clerk’s educated estimate on an arrival time of a shipment of fresh eggs may have been adequate, but not in post-covid 2020, with its shifting demands and unpredictable delays. Those guesses can’t cope with an egg packing plant shut down for a week when the virus flares up or a shipment delayed by a quarantined truck driver.

Good news

Fortunately, with the data available today, these issues are visible in supply chain tracking systems. Orders can be immediately redirected to a different packing plant that has returned from a shutdown or dispatch a fresh relief driver instead of leaving a shipment to wait in a truck stop parking lot. Issues can be resolved today that would not have been visible as issues a decade ago. Consequently, supply chains have been strikingly resilient to the covid-19 disruption.

Supply chains were much different in my pioneer grandparents’ days. They grew their own meat, poultry, and vegetables, and lived without toilet paper for most of their lives. Although supply was less complicated, the effects of supply disruption, like a punishing thunderstorm destroying a wheat crop, was as significant as today’s disruptions.

In November of 2020 with steeply rising infection counts, predictions of new supply disruption occasionally surface. The response of supply chains so far this year leave me optimistic that we have seen the worst.

Home Network Security: RedLINK™

In a previous post, I said that the Internet of Things (IoT) has increased the size and complexity of home networks. We had a new heating system installed recently that added a new dimension to our home IoT network: RedLINK ™, which, on the whole, was good for our home security.

Home network security sunrise

IoT and network complexity

As networks increase in size and complexity, they become more difficult to manage and secure. Businesses hire technicians who are trained in security to manage their networks, which is usually a spendy proposition, but there is a lot at stake and security is one of many justifiable costs of doing business that accountants and managers prepare for.

Working from home network security

At home, we are in a different position. I’m not an accountant or a tax expert, so don’t take my word for it, but if your income is from a regular paycheck, the IRS probably will not allow you to deduct expenses derived from working at home. You might be able to convince your employer to reimburse you for these expenses, but be sure that the reimbursement will not be considered taxable income. In other words, in most cases, you secure your home network on your own nickel.

When I was working from home, most years, my employer, CA Technologies, permitted me a fixed amount on my expense account that I could request for working-from-home outlays. Not all employers do that, but take advantage if you can.

Since I retired and began writing books for extra income, I have deducted some for computing, network, and office overhead every year. I keep records of business expenses and have an accountant go over them to be sure they’ll pass an audit.

Home network security challenges

As a businessman, I don’t think I could justify investing much cash in our home network security. We are not juicy hacker bait. Although a successful attack could throw us in a world of hurt, it would not give a hacker much of a payday compared to even a moderately large business or agency.

Nevertheless, I worry about the security of our network. That means home network security is a DIY project for me. Fortunately, forty or so years in the computing industry has prepared me for this.

Securing HVAC

I’m working on methods to secure home networks that folks can do for themselves. In this post I will say something about securing home heating, ventilation, and air-conditioning systems (HVAC). This is an important topic for me because we just had a new heating system installed.

I was pleased to discover that our new system uses an alternative to standard Wi-Fi for communications. Sensors and controls connect wirelessly, but not the same way the rest of our computing gear connects.

IoT and Wi-Fi

Wi-Fi, the wireless network standard that almost every home network relies on, was designed with the capacity for data flows like streaming video, which is massive overbuilding for most IoT purposes. The data passing to and from IoT devices, with the exception of remote cameras and speakers, is typically miniscule compared to Wi-Fi loads.

There are several IoT platforms available that support low bandwidth communications. Our heating system uses the Honeywell RedLINK ™ platform specifically designed to support residential heating, ventilation, and air conditioning (HVAC) systems. It uses the 900 MHz band, which is a lower frequency than most Wi-Fi.

Lower frequencies have longer range and penetrate barriers like walls more easily than higher frequency signals. Thus, lower frequencies are more reliable and cover more area. The downside of lower frequency is lower data transfer rates, but for applications that don’t transmit a lot of data, like HVAC, lower data rates are fine.

A heating system that reports temperatures and humidity every 2 minutes from several sensors spread through a house is transmitting data at a trickle compared to streaming video, audio, and even sending a moderate size word-processing file. At 900 MHz, RedLINK ™ has better wall penetration and range than Bluetooth or typical Wi-Fi, which use 2.4 GHz and higher frequency bands. Even if Wi-Fi were unreliable in our house, I would expect RedLINK ™ to be solid.

Interference on the 900 MHz band

But the 900 MHz band is crowded. To begin, it’s designated for scientific, industrial, and medical device connectivity. Some cell phone and walkie-talkie type communications use it. Wireless telephone handsets often use the 900 MHz band. Amateur radio hobbyists also are permitted to use 900 MHz band signals. Consequently, in a residence, several devices might attempt to send a signal at the same frequency within the band at the same time. Colliding signals garble the message. This shows up as interference, which could be a big problem.

Frequency hopping

RedLINK ™, like Bluetooth, and the actress Hedy Lamar’s torpedo guidance system, has another trick: frequency hopping.

The military began to develop frequency hopping before WWI to protect battlefield radio messaging. By switching frequencies quickly in unison, the signal from transmitter to receiver never lingers long enough at a given frequency to degrade the overall message.

In addition, modern communication systems divide data into small chunks called packets that can be checked for consistency and resent if necessary. The combination of packet data and frequency hopping practically eliminates interference at low data volumes.

Canada geese
Canada geese sound a little like hopping frequencies

Changing frequencies also discourages interception and listening in on messages, but, unfortunately, the technology to follow most frequency hopping schemes is freely available now, so hopping is weak security, but it does effectively squelch interference on crowded bands.

Power consumption

The 900 MHz band consumes less power than higher frequency transmissions and batteries last longer. Since I don’t relish crawling into odd corners to change batteries on remote sensors, battery life is more important to me for IoT than other applications.

Proprietary protocol

A proprietary network protocol like RedLINK™ installs more easily and reliably than Wi-Fi for HVAC, but it tends to lock consumers into a single vendor. A version of the public Wi-Fi standard designed for low volume data transmission, called Wi-Fi HaLow, exists. But I haven’t found any HaLow equipment on the market.

Hacking RedLINK ™ could be devastating, essentially allowing a malicious invader to take over our heating system, making our lives uncomfortable, possibly wrecking our heating system, or setting our house on fire. I have no doubt that a diligent enough hacker could gain entrance to a RedLINK ™ network, but it would require detailed knowledge of a proprietary system, which would require a lot of effort for a low money skill.

A sigh of relief

In fact, I breathed a sigh of relief when I found that our thermostat doesn’t use Wi-Fi to communicate with our furnace. I am far more concerned with hacking our Wi-Fi system than RedLINK ™.

Issues remain

Our smart thermostat is attractive and easy to use because it’s a small but powerful  computer. This has drawbacks. For example, I found instructions on the internet for running the video game Doom on a model similar to the thermostat in our dining room. I worked on an application twenty-five years ago to rid corporate networks of that very game.

It’s not as bad as it may appear, but rogue Doom installations bear some scrutiny, which I will do in a future post.  More important, I have not enabled or begun to explore the app that connects a smartphone or other computer to the thermostat. This is a subject for a future post and an area for caution.

Election Tampering: Y2K Fears Redux?

For the last few days, I’ve been reading reports on the Trickbot takedown. U.S. Cyber Command and Microsoft have been hitting the large botnet, called Trickbot, that is controlled from eastern Europe, most likely Russia, and appears to have been maneuvering to interfere with the November 3rd U.S. election. The takedown steps apparently were planned strategically to give the botmasters little time to rebuild before the election. I sincerely hope the strategy succeeds. And I hope, and believe, that the Trickbot takedown is only the tip of an iceberg in a battle that is freezing out cyberattacks on our election.

We survived Y2K fears.

Trickbot

Trickbot, a botnet, is a multi-purpose covert criminal supercomputer cobbled together from thousands of hacked Windows computers. The botnet’s design offers few clues to hack victims that their devices are secret participants in criminal cyber attacks. The Trickbot crimes are mostly ransomware exploits for illegal profit. For some background on botnets see Home Network Setup: Smart Kitchen Crisis.

Y2K fears

The reports reminded me of Y2K fears, the year 2000 computer scare of 20 years ago. I hope those efforts are as successful as the Y2K remediation, which were so successful, Y2K was called a hoax by those who did not understand the computer industry.

Y2K and Bolivian basket weavers

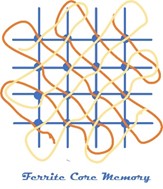
I remember the Y2K affair well. It was no hoax. Everyone in the computing industry knew trouble was coming. Already in the early 1980s the issue was a hot topic among engineers. The problem went back to the early days of computing when data storage was expensive. It’s hard to believe today, but in the early days, the fastest and most reliable computer memory was hand-crafted by weavers from copper wire and tiny donut shaped ferrite magnets called cores. My meatware memory is not entirely reliable, but I remember hearing that Bolivian basket weavers were recruited to manufacture woven core memory. The computers on the Apollo moon mission were based on hard-wired ferrite cores.

Today, we talk about terabytes (trillions of bytes) but in those days, even a single K (1012 bytes) of memory cost thousands of dollars. I guess everyone today knows that a byte is eight bits, a sequence of eight 0s and 1s. Each donut magnet in core memory represented a single 0 or 1. The costing rule of thumb for handcrafted core memory was $1 a bit. At that price, a terabyte of memory would cost 8 trillion dollars, roughly the market price of 8 Amazons.

In the 1960s and 70s, programmers did not waste storage. They saved a few bytes by storing the year as two digits. 1913 was “13” and 1967 was “67.”

Most business programs used “binary coded decimal.” Storing the year as 2 digits instead of 4 was a savings of 8 bits: at near eight bucks a bit, close to $70 in 2020 dollars. Put another way, today, the price of those two 1970 bytes will buy 2 terabytes of flash memory, delivered to your door by Amazon. That flash memory would have cost 16 trillion dollars in 1970, filled several warehouses, and probably generated enough heat to warm New England for the winter.

Dates and the year 2000

Dates are used heavily in business computing, somewhat less in scientific computing. Accounting, scheduling, supply chain management all depend on date calculations. Today most of these calculations are handled in a few standard code libraries that are used over and over, but those libraries did not exist when the programs that ran the world’s business in 1999 were written. Each time a program needed a date calculation, a programmer wrote code.

Man, did they write code. Programmers delight in rolling their own, writing their own code. Coming up with an entirely original mundane date calculation will make a skilled coder’s heart sing. And there is joy in writing code that looks like it does one thing and does something quite different. These tastes decree that given an opportunity, coders will come up with many obscure and abstruse ways to calculate and analyze dates.

When I was hiring coders, I challenged candidates to describe an algorithm to determine the late fee on an invoice payment if 1% was to be added for each calendar month that had passed after the date the invoice was cut. If you think that description’s a little vague, you’re right. A hidden part of the challenge was for the coder to determine exactly what I had asked for. I don’t believe I ever got two identical solutions, and some would have behaved wildly if the calculations had crossed the Y2K boundary.

The industry took Y2K seriously

For good reason, in the late nineties, the industry got serious about the approaching crisis.

Y2K was a big deal. By 1995, I, along with many of my colleagues, had intentionally forgotten how to code in COBOL, the mainframe programming language of most 20th century business programs that were at the heart of Y2K issues. I won’t say that COBOL is a bad language, but few programmers cared for its wordy style. The scarcity of COBOL programmers elevated the language to a money skill in the last days of the century.

Y2K in my products

At that time, I was managing the development of a service desk product that I had designed several years before. I was coding almost exclusively in C++ on Unix and Windows, which uses an internal representation for dates and times that would not, in theory, have Y2K problems.

Nevertheless, management, who didn’t know that our product was theoretically immune to Y2K, declared my Fiscal Year 2000 bonus would depend on the absence of Y2K errors in our code. I smiled when I read the letter that described my bonus terms. Most years, fickle market conditions that I could not influence decided my bonus. This time, my bonus was in the bag due to a wise previous decision to build on a platform that sidestepped the central Y2K issue.

Still, I don’t mess around with my bonus. I started feeding Y2K use cases into our test plans, just to be sure.

I’m glad I did. Management, bless their bottom-line focused hearts, were right to worry about Y2K. It’s been a long time, but I estimate my team spotted and fixed a dozen significant Y2K defects that could have brought the product down or caused crippling errors.

Our defects were not COBOL style issues, but they stemmed from the two-digit year mindset that then pervaded business coding. For example, serial numbers often embed a two-digit year somewhere. A clever developer might use that fact and create a Y2K defect from it.

If those dozen defects had kicked in simultaneously on New Year’s Eve, service desks would have begun failing mid-Pacific in a pattern that would repeat itself as New Year’s Day followed the sun around the globe to Hawaii the next day. That was in a product running on platforms that were supposedly immune to Y2K errors. The devil in it was that a service desk would be used to manage the response to incidents that arose from other Y2K system crashes, compounding the chaos.

A real threat

People who are not responsible for building and maintaining computer systems probably don’t realize what happens when a raft of defects appear at the same time. Troubleshooting the origin of a malfunction caused by a single mistake can be difficult. With two mistakes, the problem becomes more complex and confusing. Each added source compounds the difficulty. At a certain point, the system seems to behave randomly, and you want to delete the whole thing and start over.

In the bad old days, we often saw large software projects break in dozens of places at once when we fired up them up for the first time. We used to call it “big bang” testing. Since writing code is more fun than testing code, many developers embraced the methodology and put off testing. But untested code is buggy code. Those big bangs were intractable messes of defects that could take weeks and months to untangle. We soon learned to test small units of code early and often, before mild-mannered projects became monsters.

As testing proceeded in development labs, engineers began to recognize that Y2K threatened to be a mass conflagration like those big bang debacles. Worse. Y2K bugs were everywhere. Their corruption extended to hundreds of systems. Unremediated Y2K threatened software mayhem like I have never seen and hope to never to see.

The reaction

Some engineers seized the limelight by overreacting. Doomsday prophets got wind of what was happening in development labs all over the globe. They went to the media with predictions of the imminent collapse of financial systems, communications, and power grids, which threatened to halt the economy and provoke the mother of all economic disasters. ATMs and traffic lights were about to go out of control. The preppers stockpiled guns, freeze-dried chili, and toilet paper enough to isolate for months.

Y2K at CA Technologies

I checked in to the CA Technologies (then Computer Associates) development lab in Kirkland on the Seattle east side early in the morning of December 31, 1999. As the senior technology manager in Seattle, I had orders to gather a team of developers and support people to man an emergency response hotline. The idea was that any Computer Associates customer with any Y2K problem could call the hotline and get expert help. Most engineers thought this was a transparent marketing ploy to take advantage of fears that had been whipped to a frenzy by the doomsday crowd.

Highly publicized orders were issued that development teams were on the hook until the last Y2K customer issue was resolved. The company supplied special Y2K tee-shirts. A buffet of sandwiches and periodic deliveries of pizza and other snacks were set up in a large conference room we called the board room. A closed-circuit television feed from headquarters in New York was beamed onto a then-rare wall-sized flat video screen. Rumor said champagne was scheduled to arrive at midnight.

The big letdown

I honestly can’t remember if the bubbly ever appeared. Late in the afternoon, I told all my crew they could leave if they wanted. I had to stay until midnight, but there was no reason to spoil their New Year’s celebration.

Why? On the Pacific Coast, we were among the last time zones to flip to 2000. In the morning, a customer called to headquarters in New York with a minor problem in Australia. It was fixed in minutes–mostly a user misunderstanding as I recall. The Kirkland team was not called on once. Typical developers, the crew loaded up on free sandwiches and pizza, took the loot to their cubicles and silently worked on code. A few salespeople wandered in to check on the action; there was none.

After all the buildup, why the big meh? Because humans aren’t stupid. The industry responded to the danger with testing and fixing. I’ve seen and believe estimates that upwards of $200 billion were spent on Y2K remediation in the 1990s. That was money well-spent. Consequently, Y2K came and went with barely a ripple.

The Y2K hoax

I take it back about humans not being stupid. We immediately began to hear about the Y2K hoax, a conspiracy and scare tactic for whatever purpose the speaker or writer found convenient. I’m sure the loudest criers of hoax were the same loudmouths who screamed computer Armageddon. I’d like to roll back the calendar and give the world a taste of what would have happened if Y2K had been ignored.

Actually, I wish Y2K had been ignored outside the industry and the people who understood the problem were allowed to quietly fix it without all the noise.

But that wouldn’t be right either. We were not heroes. The cost of the Y2K remediation was the price of poor judgement. Acting as if it did not occur would only encourage future bad choices. The remediation was nothing to be proud of. The industry should be called to account.

Nonetheless, in my dark moments, I have no patience for people who broadcast opinions but don’t carry water, put out fires, and make things work. Not everyone was fortunate enough to be in on the action of Y2K, not everyone has the training and experience to know what it takes to keep our computer-dependent society viable.

Y2K and the general election

Which brings us back to the Trickbot takedown. November 3rd 2020 has begun to smell to me like the approach of January 1st 2000. I see real danger and a dead serious response. I’m not an active member of the cybersecurity community, but I keep up. I have no doubt that criminals, extremists from every corner of the political spectrum, and foreign nation-states are planning cyber attacks to extort payments from election agencies, stop people from voting, slow vote tallies, and question results.

Election tampering hoax

But I also see the seriousness and competence of the efforts to prevent and neutralize these bad actors. Some signs point to success. Already, two weeks before the election, 29 million voters have voted, almost five times the number that had voted at this point in 2016. I’m sure election day will be tough, but I will not be the least surprised to hear another big meh on November 4, followed by cries of “election interference hoax!” from every direction, but from my vantage now, it’s clear it is no hoax.

But I hope it looks like a hoax.